Databricks-Machine-Learning-Associate試験無料問題集「Databricks Certified Machine Learning Associate 認定」
A data scientist is using MLflow to track their machine learning experiment. As a part of each of their MLflow runs, they are performing hyperparameter tuning. The data scientist would like to have one parent run for the tuning process with a child run for each unique combination of hyperparameter values. All parent and child runs are being manually started with mlflow.start_run.
Which of the following approaches can the data scientist use to accomplish this MLflow run organization?
Which of the following approaches can the data scientist use to accomplish this MLflow run organization?
正解:B
解答を投票する
解説: (GoShiken メンバーにのみ表示されます)
A machine learning engineer has been notified that a new Staging version of a model registered to the MLflow Model Registry has passed all tests. As a result, the machine learning engineer wants to put this model into production by transitioning it to the Production stage in the Model Registry.
From which of the following pages in Databricks Machine Learning can the machine learning engineer accomplish this task?
From which of the following pages in Databricks Machine Learning can the machine learning engineer accomplish this task?
正解:C
解答を投票する
解説: (GoShiken メンバーにのみ表示されます)
A data scientist is using Spark ML to engineer features for an exploratory machine learning project.
They decide they want to standardize their features using the following code block:
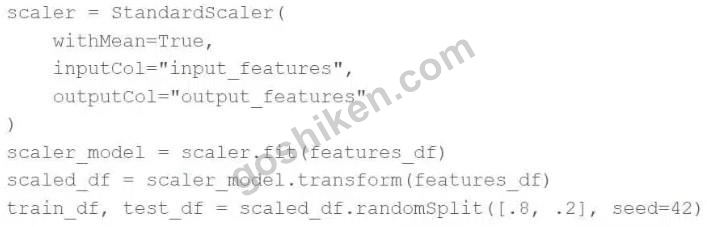
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.
Which of the following changes can the data scientist make to address the concern?
They decide they want to standardize their features using the following code block:
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.
Which of the following changes can the data scientist make to address the concern?
正解:C
解答を投票する
解説: (GoShiken メンバーにのみ表示されます)
A data scientist wants to efficiently tune the hyperparameters of a scikit-learn model in parallel. They elect to use the Hyperopt library to facilitate this process.
Which of the following Hyperopt tools provides the ability to optimize hyperparameters in parallel?
Which of the following Hyperopt tools provides the ability to optimize hyperparameters in parallel?
正解:B
解答を投票する
解説: (GoShiken メンバーにのみ表示されます)
A data scientist is wanting to explore summary statistics for Spark DataFrame spark_df. The data scientist wants to see the count, mean, standard deviation, minimum, maximum, and interquartile range (IQR) for each numerical feature.
Which of the following lines of code can the data scientist run to accomplish the task?
Which of the following lines of code can the data scientist run to accomplish the task?
正解:B
解答を投票する
解説: (GoShiken メンバーにのみ表示されます)
A machine learning engineer is trying to scale a machine learning pipeline pipeline that contains multiple feature engineering stages and a modeling stage. As part of the cross-validation process, they are using the following code block:
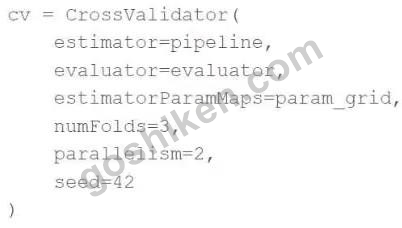
A colleague suggests that the code block can be changed to speed up the tuning process by passing the model object to the estimator parameter and then placing the updated cv object as the final stage of the pipeline in place of the original model.
Which of the following is a negative consequence of the approach suggested by the colleague?
A colleague suggests that the code block can be changed to speed up the tuning process by passing the model object to the estimator parameter and then placing the updated cv object as the final stage of the pipeline in place of the original model.
Which of the following is a negative consequence of the approach suggested by the colleague?
正解:E
解答を投票する
解説: (GoShiken メンバーにのみ表示されます)
A health organization is developing a classification model to determine whether or not a patient currently has a specific type of infection. The organization's leaders want to maximize the number of positive cases identified by the model.
Which of the following classification metrics should be used to evaluate the model?
Which of the following classification metrics should be used to evaluate the model?
正解:A
解答を投票する
解説: (GoShiken メンバーにのみ表示されます)
A machine learning engineer is using the following code block to scale the inference of a single-node model on a Spark DataFrame with one million records:
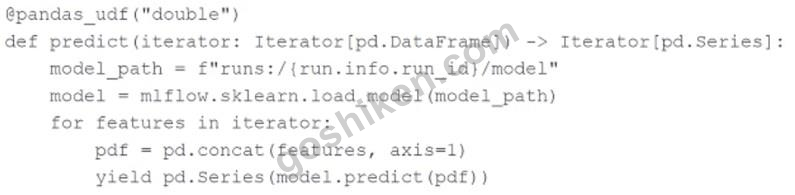
Assuming the default Spark configuration is in place, which of the following is a benefit of using an Iterator?
Assuming the default Spark configuration is in place, which of the following is a benefit of using an Iterator?
正解:B
解答を投票する
解説: (GoShiken メンバーにのみ表示されます)