
Databricks Databricks-Machine-Learning-Associate問題集で100%カバー率リアル試験問題(更新された76問あります)
リアルDatabricks-Machine-Learning-Associate問題集でリアルDatabricks問題集PDF
質問 # 29
A data scientist has developed a linear regression model using Spark ML and computed the predictions in a Spark DataFrame preds_df with the following schema:
prediction DOUBLE
actual DOUBLE
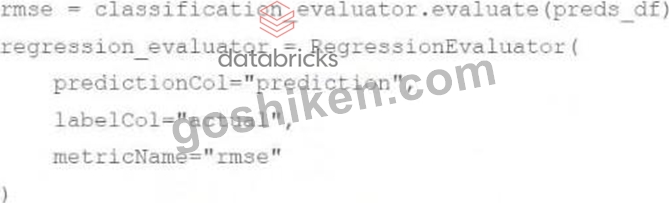
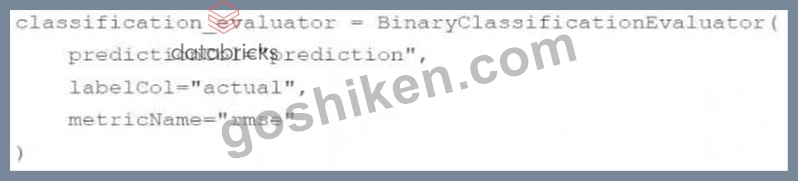
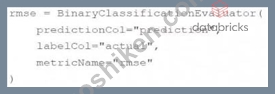
Which of the following code blocks can be used to compute the root mean-squared-error of the model according to the data in preds_df and assign it to the rmse variable?
- A.
- B.

- C.
- D.
正解:B
解説:
The code block to compute the root mean-squared error (RMSE) for a linear regression model in Spark ML should use the RegressionEvaluator class with metricName set to "rmse". Given the schema of preds_df with columns prediction and actual, the correct evaluator setup will specify predictionCol="prediction" and labelCol="actual". Thus, the appropriate code block (Option C in your list) that uses RegressionEvaluator to compute the RMSE is the correct choice. This setup correctly measures the performance of the regression model using the predictions and actual outcomes from the DataFrame.
Reference:
Spark ML documentation (Using RegressionEvaluator to Compute RMSE).
質問 # 30
A data scientist is wanting to explore the Spark DataFrame spark_df. The data scientist wants visual histograms displaying the distribution of numeric features to be included in the exploration.
Which of the following lines of code can the data scientist run to accomplish the task?
- A. spark_df.summary()
- B. dbutils.data.summarize (spark_df)
- C. dbutils.data(spark_df).summarize()
- D. spark_df.describe()
- E. This task cannot be accomplished in a single line of code.
正解:B
解説:
To display visual histograms and summaries of the numeric features in a Spark DataFrame, the Databricks utility function dbutils.data.summarize can be used. This function provides a comprehensive summary, including visual histograms.
Correct code:
dbutils.data.summarize(spark_df)
Other options like spark_df.describe() and spark_df.summary() provide textual statistical summaries but do not include visual histograms.
Reference:
Databricks Utilities Documentation
質問 # 31
Which of the following tools can be used to distribute large-scale feature engineering without the use of a UDF or pandas Function API for machine learning pipelines?
- A. pandas
- B. Scikit-learn
- C. Keras
- D. PvTorch
- E. Spark ML
正解:E
解説:
Spark ML (Machine Learning Library) is designed specifically for handling large-scale data processing and machine learning tasks directly within Apache Spark. It provides tools and APIs for large-scale feature engineering without the need to rely on user-defined functions (UDFs) or pandas Function API, allowing for more scalable and efficient data transformations directly distributed across a Spark cluster. Unlike Keras, pandas, PyTorch, and scikit-learn, Spark ML operates natively in a distributed environment suitable for big data scenarios.
Reference:
Spark MLlib documentation (Feature Engineering with Spark ML).
質問 # 32
A data scientist wants to tune a set of hyperparameters for a machine learning model. They have wrapped a Spark ML model in the objective function objective_function and they have defined the search space search_space.
As a result, they have the following code block: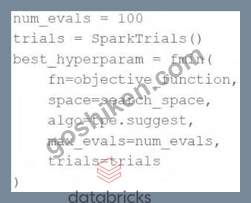
Which of the following changes do they need to make to the above code block in order to accomplish the task?
- A. Reduce num_evals to be less than 10
- B. Change SparkTrials() to Trials()
- C. Remove the algo=tpe.suggest argument
- D. Remove the trials=trials argument
- E. Change fmin() to fmax()
正解:B
解説:
The SparkTrials() is used to distribute trials of hyperparameter tuning across a Spark cluster. If the environment does not support Spark or if the user prefers not to use distributed computing for this purpose, switching to Trials() would be appropriate. Trials() is the standard class for managing search trials in Hyperopt but does not distribute the computation. If the user is encountering issues with SparkTrials() possibly due to an unsupported configuration or an error in the cluster setup, using Trials() can be a suitable change for running the optimization locally or in a non-distributed manner.
Reference
Hyperopt documentation: http://hyperopt.github.io/hyperopt/
質問 # 33
A machine learning engineer is using the following code block to scale the inference of a single-node model on a Spark DataFrame with one million records: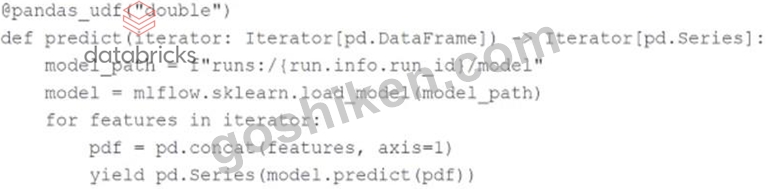
Assuming the default Spark configuration is in place, which of the following is a benefit of using an Iterator?
- A. The data will be distributed across multiple executors during the inference process
- B. The model will be limited to a single executor preventing the data from being distributed
- C. The model only needs to be loaded once per executor rather than once per batch during the inference process
- D. The data will be limited to a single executor preventing the model from being loaded multiple times
正解:C
解説:
Using an iterator in the pandas_udf ensures that the model only needs to be loaded once per executor rather than once per batch. This approach reduces the overhead associated with repeatedly loading the model during the inference process, leading to more efficient and faster predictions. The data will be distributed across multiple executors, but each executor will load the model only once, optimizing the inference process.
Reference:
Databricks documentation on pandas UDFs: Pandas UDFs
質問 # 34
A data scientist is attempting to tune a logistic regression model logistic using scikit-learn. They want to specify a search space for two hyperparameters and let the tuning process randomly select values for each evaluation.
They attempt to run the following code block, but it does not accomplish the desired task: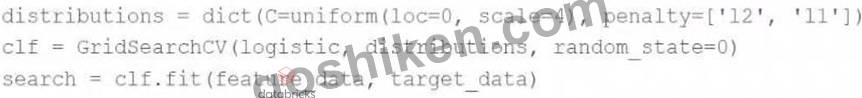
Which of the following changes can the data scientist make to accomplish the task?
- A. Replace the GridSearchCV operation with RandomizedSearchCV
- B. Replace the random_state=0 argument with random_state=1
- C. Replace the GridSearchCV operation with cross_validate
- D. Replace the penalty= ['12', '11'] argument with penalty=uniform ('12', '11')
- E. Replace the GridSearchCV operation with ParameterGrid
正解:A
解説:
The user wants to specify a search space for hyperparameters and let the tuning process randomly select values. GridSearchCV systematically tries every combination of the provided hyperparameter values, which can be computationally expensive and time-consuming. RandomizedSearchCV, on the other hand, samples hyperparameters from a distribution for a fixed number of iterations. This approach is usually faster and still can find very good parameters, especially when the search space is large or includes distributions.
Reference
Scikit-Learn documentation on hyperparameter tuning: https://scikit-learn.org/stable/modules/grid_search.html#randomized-parameter-optimization
質問 # 35
A data scientist has developed a machine learning pipeline with a static input data set using Spark ML, but the pipeline is taking too long to process. They increase the number of workers in the cluster to get the pipeline to run more efficiently. They notice that the number of rows in the training set after reconfiguring the cluster is different from the number of rows in the training set prior to reconfiguring the cluster.
Which of the following approaches will guarantee a reproducible training and test set for each model?
- A. Manually partition the input data
- B. Manually configure the cluster
- C. Write out the split data sets to persistent storage
- D. Set a speed in the data splitting operation
正解:C
解説:
To ensure reproducible training and test sets, writing the split data sets to persistent storage is a reliable approach. This allows you to consistently load the same training and test data for each model run, regardless of cluster reconfiguration or other changes in the environment.
Correct approach:
Split the data.
Write the split data to persistent storage (e.g., HDFS, S3).
Load the data from storage for each model training session.
train_df, test_df = spark_df.randomSplit([0.8, 0.2], seed=42) train_df.write.parquet("path/to/train_df.parquet") test_df.write.parquet("path/to/test_df.parquet") # Later, load the data train_df = spark.read.parquet("path/to/train_df.parquet") test_df = spark.read.parquet("path/to/test_df.parquet") Reference:
Spark DataFrameWriter Documentation
質問 # 36
Which of the following describes the relationship between native Spark DataFrames and pandas API on Spark DataFrames?
- A. pandas API on Spark DataFrames are single-node versions of Spark DataFrames with additional metadata
- B. pandas API on Spark DataFrames are more performant than Spark DataFrames
- C. pandas API on Spark DataFrames are unrelated to Spark DataFrames
- D. pandas API on Spark DataFrames are made up of Spark DataFrames and additional metadata
- E. pandas API on Spark DataFrames are less mutable versions of Spark DataFrames
正解:D
解説:
Pandas API on Spark (previously known as Koalas) provides a pandas-like API on top of Apache Spark. It allows users to perform pandas operations on large datasets using Spark's distributed compute capabilities. Internally, it uses Spark DataFrames and adds metadata that facilitates handling operations in a pandas-like manner, ensuring compatibility and leveraging Spark's performance and scalability.
Reference
pandas API on Spark documentation: https://spark.apache.org/docs/latest/api/python/user_guide/pandas_on_spark/index.html
質問 # 37
A data scientist wants to efficiently tune the hyperparameters of a scikit-learn model in parallel. They elect to use the Hyperopt library to facilitate this process.
Which of the following Hyperopt tools provides the ability to optimize hyperparameters in parallel?
- A. SparkTrials
- B. search_space
- C. objective_function
- D. quniform
- E. fmin
正解:A
解説:
The SparkTrials class in the Hyperopt library allows for parallel hyperparameter optimization on a Spark cluster. This enables efficient tuning of hyperparameters by distributing the optimization process across multiple nodes in a cluster.
from hyperopt import fmin, tpe, hp, SparkTrials search_space = { 'x': hp.uniform('x', 0, 1), 'y': hp.uniform('y', 0, 1) } def objective(params): return params['x'] ** 2 + params['y'] ** 2 spark_trials = SparkTrials(parallelism=4) best = fmin(fn=objective, space=search_space, algo=tpe.suggest, max_evals=100, trials=spark_trials) Reference:
Hyperopt Documentation
質問 # 38
A data scientist has been given an incomplete notebook from the data engineering team. The notebook uses a Spark DataFrame spark_df on which the data scientist needs to perform further feature engineering. Unfortunately, the data scientist has not yet learned the PySpark DataFrame API.
Which of the following blocks of code can the data scientist run to be able to use the pandas API on Spark?
- A. import pandas as pd
df = pd.DataFrame(spark_df) - B. spark_df.to_pandas()
- C. import pyspark.pandas as ps
df = ps.DataFrame(spark_df) - D. import pyspark.pandas as ps
df = ps.to_pandas(spark_df)
正解:C
解説:
To use the pandas API on Spark, the data scientist can run the following code block:
import pyspark.pandas as ps df = ps.DataFrame(spark_df)
This code imports the pandas API on Spark and converts the Spark DataFrame spark_df into a pandas-on-Spark DataFrame, allowing the data scientist to use familiar pandas functions for further feature engineering.
Reference:
Databricks documentation on pandas API on Spark: pandas API on Spark
質問 # 39
A data scientist has developed a linear regression model using Spark ML and computed the predictions in a Spark DataFrame preds_df with the following schema:
prediction DOUBLE
actual DOUBLE
Which of the following code blocks can be used to compute the root mean-squared-error of the model according to the data in preds_df and assign it to the rmse variable?
- A.
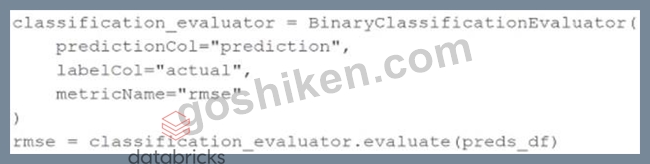
- B.
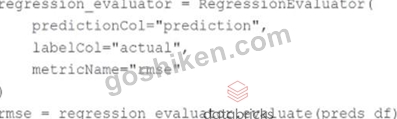
- C.
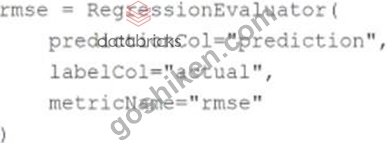
- D.
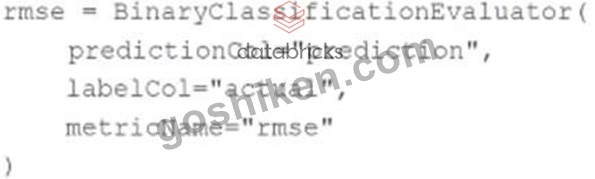
正解:B
解説:
To compute the root mean-squared-error (RMSE) of a linear regression model using Spark ML, the RegressionEvaluator class is used. The RegressionEvaluator is specifically designed for regression tasks and can calculate various metrics, including RMSE, based on the columns containing predictions and actual values.
The correct code block to compute RMSE from the preds_df DataFrame is:
regression_evaluator = RegressionEvaluator( predictionCol="prediction", labelCol="actual", metricName="rmse" ) rmse = regression_evaluator.evaluate(preds_df) This code creates an instance of RegressionEvaluator, specifying the prediction and label columns, as well as the metric to be computed ("rmse"). It then evaluates the predictions in preds_df and assigns the resulting RMSE value to the rmse variable.
Options A and B incorrectly use BinaryClassificationEvaluator, which is not suitable for regression tasks. Option D also incorrectly uses BinaryClassificationEvaluator.
Reference:
PySpark ML Documentation
質問 # 40
A data scientist has written a feature engineering notebook that utilizes the pandas library. As the size of the data processed by the notebook increases, the notebook's runtime is drastically increasing, but it is processing slowly as the size of the data included in the process increases.
Which of the following tools can the data scientist use to spend the least amount of time refactoring their notebook to scale with big data?
- A. pandas API on Spark
- B. Feature Store
- C. PySpark DataFrame API
- D. Spark SQL
正解:A
解説:
The pandas API on Spark provides a way to scale pandas operations to big data while minimizing the need for refactoring existing pandas code. It allows users to run pandas operations on Spark DataFrames, leveraging Spark's distributed computing capabilities to handle large datasets more efficiently. This approach requires minimal changes to the existing code, making it a convenient option for scaling pandas-based feature engineering notebooks.
Reference:
Databricks documentation on pandas API on Spark: pandas API on Spark
質問 # 41
A data scientist has defined a Pandas UDF function predict to parallelize the inference process for a single-node model: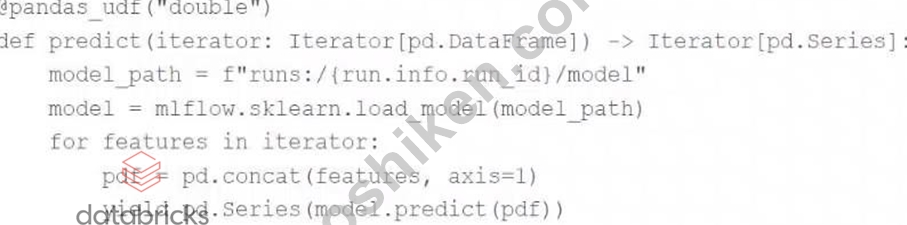
They have written the following incomplete code block to use predict to score each record of Spark DataFrame spark_df: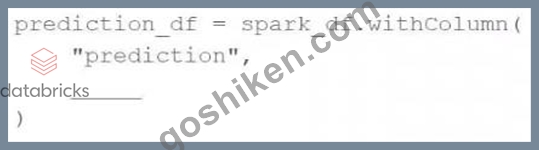
Which of the following lines of code can be used to complete the code block to successfully complete the task?
- A. predict(Iterator(spark_df))
- B. mapInPandas(predict(spark_df.columns))
- C. mapInPandas(predict)
- D. predict(*spark_df.columns)
- E. predict(spark_df.columns)
正解:C
解説:
To apply the Pandas UDF predict to each record of a Spark DataFrame, you use the mapInPandas method. This method allows the Pandas UDF to operate on partitions of the DataFrame as pandas DataFrames, applying the specified function (predict in this case) to each partition. The correct code completion to execute this is simply mapInPandas(predict), which specifies the UDF to use without additional arguments or incorrect function calls.
Reference:
PySpark DataFrame documentation (Using mapInPandas with UDFs).
質問 # 42
The implementation of linear regression in Spark ML first attempts to solve the linear regression problem using matrix decomposition, but this method does not scale well to large datasets with a large number of variables.
Which of the following approaches does Spark ML use to distribute the training of a linear regression model for large data?
- A. Least-squares method
- B. Singular value decomposition
- C. Logistic regression
- D. Iterative optimization
正解:D
解説:
For large datasets, Spark ML uses iterative optimization methods to distribute the training of a linear regression model. Specifically, Spark MLlib employs techniques like Stochastic Gradient Descent (SGD) and Limited-memory Broyden-Fletcher-Goldfarb-Shanno (L-BFGS) optimization to iteratively update the model parameters. These methods are well-suited for distributed computing environments because they can handle large-scale data efficiently by processing mini-batches of data and updating the model incrementally.
Reference:
Databricks documentation on linear regression: Linear Regression in Spark ML
質問 # 43
Which of the following tools can be used to parallelize the hyperparameter tuning process for single-node machine learning models using a Spark cluster?
- A. Autoscaling clusters
- B. MLflow Experiment Tracking
- C. Delta Lake
- D. Autoscaling clusters
- E. Spark ML
正解:E
解説:
Spark ML (part of Apache Spark's MLlib) is designed to handle machine learning tasks across multiple nodes in a cluster, effectively parallelizing tasks like hyperparameter tuning. It supports various machine learning algorithms that can be optimized over a Spark cluster, making it suitable for parallelizing hyperparameter tuning for single-node machine learning models when they are adapted to run on Spark.
Reference
Apache Spark MLlib Guide: https://spark.apache.org/docs/latest/ml-guide.html Spark ML is a library within Apache Spark designed for scalable machine learning. It provides tools to handle large-scale machine learning tasks, including parallelizing the hyperparameter tuning process for single-node machine learning models using a Spark cluster. Here's a detailed explanation of how Spark ML can be used:
Hyperparameter Tuning with CrossValidator: Spark ML includes the CrossValidator and TrainValidationSplit classes, which are used for hyperparameter tuning. These classes can evaluate multiple sets of hyperparameters in parallel using a Spark cluster.
from pyspark.ml.tuning import CrossValidator, ParamGridBuilder
from pyspark.ml.evaluation import BinaryClassificationEvaluator
# Define the model
model = ...
# Create a parameter grid
paramGrid = ParamGridBuilder() \
.addGrid(model.hyperparam1, [value1, value2]) \
.addGrid(model.hyperparam2, [value3, value4]) \
.build()
# Define the evaluator
evaluator = BinaryClassificationEvaluator()
# Define the CrossValidator
crossval = CrossValidator(estimator=model,
estimatorParamMaps=paramGrid,
evaluator=evaluator,
numFolds=3)
Parallel Execution: Spark distributes the tasks of training models with different hyperparameters across the cluster's nodes. Each node processes a subset of the parameter grid, which allows multiple models to be trained simultaneously.
Scalability: Spark ML leverages the distributed computing capabilities of Spark. This allows for efficient processing of large datasets and training of models across many nodes, which speeds up the hyperparameter tuning process significantly compared to single-node computations.
Reference
Apache Spark MLlib Documentation
Hyperparameter Tuning in Spark ML
質問 # 44
An organization is developing a feature repository and is electing to one-hot encode all categorical feature variables. A data scientist suggests that the categorical feature variables should not be one-hot encoded within the feature repository.
Which of the following explanations justifies this suggestion?
- A. One-hot encoding is not a common strategy for representing categorical feature variables numerically.
- B. One-hot encoding is computationally intensive and should only be performed on small samples of training sets for individual machine learning problems.
- C. One-hot encoding is dependent on the target variable's values which differ for each apaplication.
- D. One-hot encoding is a potentially problematic categorical variable strategy for some machine learning algorithms.
正解:D
解説:
The suggestion not to one-hot encode categorical feature variables within the feature repository is justified because one-hot encoding can be problematic for some machine learning algorithms. Specifically, one-hot encoding increases the dimensionality of the data, which can be computationally expensive and may lead to issues such as multicollinearity and overfitting. Additionally, some algorithms, such as tree-based methods, can handle categorical variables directly without requiring one-hot encoding.
Reference:
Databricks documentation on feature engineering: Feature Engineering
質問 # 45
A data scientist wants to use Spark ML to impute missing values in their PySpark DataFrame features_df. They want to replace missing values in all numeric columns in features_df with each respective numeric column's median value.
They have developed the following code block to accomplish this task: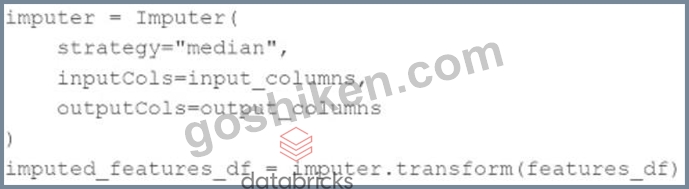
The code block is not accomplishing the task.
Which reasons describes why the code block is not accomplishing the imputation task?
- A. The inputCols and outputCols need to be exactly the same.
- B. The fit method needs to be called instead of transform.
- C. It does not fit the imputer on the data to create an ImputerModel.
- D. It does not impute both the training and test data sets.
正解:C
解説:
In the provided code block, the Imputer object is created but not fitted on the data to generate an ImputerModel. The transform method is being called directly on the Imputer object, which does not yet contain the fitted median values needed for imputation. The correct approach is to fit the imputer on the dataset first.
Corrected code:
imputer = Imputer( strategy="median", inputCols=input_columns, outputCols=output_columns ) imputer_model = imputer.fit(features_df) # Fit the imputer to the data imputed_features_df = imputer_model.transform(features_df) # Transform the data using the fitted imputer Reference:
PySpark ML Documentation
質問 # 46
Which of the following evaluation metrics is not suitable to evaluate runs in AutoML experiments for regression problems?
- A. R-squared
- B. MSE
- C. MAE
- D. F1
正解:D
解説:
The code block provided by the machine learning engineer will perform the desired inference when the Feature Store feature set was logged with the model at model_uri. This ensures that all necessary feature transformations and metadata are available for the model to make predictions. The Feature Store in Databricks allows for seamless integration of features and models, ensuring that the required features are correctly used during inference.
Reference:
Databricks documentation on Feature Store: Feature Store in Databricks
質問 # 47
A new data scientist has started working on an existing machine learning project. The project is a scheduled Job that retrains every day. The project currently exists in a Repo in Databricks. The data scientist has been tasked with improving the feature engineering of the pipeline's preprocessing stage. The data scientist wants to make necessary updates to the code that can be easily adopted into the project without changing what is being run each day.
Which approach should the data scientist take to complete this task?
- A. They can create a new branch in Databricks, commit their changes, and push those changes to the Git provider.
- B. They can clone the notebooks in the repository into a Databricks Workspace folder and make the necessary changes.
- C. They can create a new Git repository, import it into Databricks, and copy and paste the existing code from the original repository before making changes.
- D. They can clone the notebooks in the repository into a new Databricks Repo and make the necessary changes.
正解:A
解説:
The best approach for the data scientist to take in this scenario is to create a new branch in Databricks, commit their changes, and push those changes to the Git provider. This approach allows the data scientist to make updates and improvements to the feature engineering part of the preprocessing pipeline without affecting the main codebase that runs daily. By creating a new branch, they can work on their changes in isolation. Once the changes are ready and tested, they can be merged back into the main branch through a pull request, ensuring a smooth integration process and allowing for code review and collaboration with other team members.
Reference:
Databricks documentation on Git integration: Databricks Repos
質問 # 48
Which of the following describes the relationship between native Spark DataFrames and pandas API on Spark DataFrames?
- A. pandas API on Spark DataFrames are single-node versions of Spark DataFrames with additional metadata
- B. pandas API on Spark DataFrames are more performant than Spark DataFrames
- C. pandas API on Spark DataFrames are made up of Spark DataFrames and additional metadata
- D. pandas API on Spark DataFrames are less mutable versions of Spark DataFrames
正解:C
解説:
The pandas API on Spark DataFrames are made up of Spark DataFrames with additional metadata. The pandas API on Spark aims to provide the pandas-like experience with the scalability and distributed nature of Spark. It allows users to work with pandas functions on large datasets by leveraging Spark's underlying capabilities.
Reference:
Databricks documentation on pandas API on Spark: pandas API on Spark
質問 # 49
In which of the following situations is it preferable to impute missing feature values with their median value over the mean value?
- A. When the features are of the categorical type
- B. When the features are of the boolean type
- C. When the features contain no outliers
- D. When the features contain a lot of extreme outliers
- E. When the features contain no missing no values
正解:D
解説:
Imputing missing values with the median is often preferred over the mean in scenarios where the data contains a lot of extreme outliers. The median is a more robust measure of central tendency in such cases, as it is not as heavily influenced by outliers as the mean. Using the median ensures that the imputed values are more representative of the typical data point, thus preserving the integrity of the dataset's distribution. The other options are not specifically relevant to the question of handling outliers in numerical data.
Reference:
Data Imputation Techniques (Dealing with Outliers).
質問 # 50
A machine learning engineer has identified the best run from an MLflow Experiment. They have stored the run ID in the run_id variable and identified the logged model name as "model". They now want to register that model in the MLflow Model Registry with the name "best_model".
Which lines of code can they use to register the model associated with run_id to the MLflow Model Registry?
- A. mlflow.register_model(f"runs:/{run_id}/model", "best_model")
- B. mlflow.register_model(run_id, "best_model")
- C. mlflow.register_model(f"runs:/{run_id}/best_model", "model")
- D. millow.register_model(f"runs:/{run_id)/model")
正解:A
解説:
To register a model that has been identified by a specific run_id in the MLflow Model Registry, the appropriate line of code is:
mlflow.register_model(f"runs:/{run_id}/model", "best_model")
This code correctly specifies the path to the model within the run (runs:/{run_id}/model) and registers it under the name "best_model" in the Model Registry. This allows the model to be tracked, managed, and transitioned through different stages (e.g., Staging, Production) within the MLflow ecosystem.
Reference
MLflow documentation on model registry: https://www.mlflow.org/docs/latest/model-registry.html#registering-a-model
質問 # 51
A data scientist uses 3-fold cross-validation and the following hyperparameter grid when optimizing model hyperparameters via grid search for a classification problem:
* Hyperparameter 1: [2, 5, 10]
* Hyperparameter 2: [50, 100]
Which of the following represents the number of machine learning models that can be trained in parallel during this process?
- A. 0
- B. 1
- C. 2
- D. 3
正解:A
解説:
To determine the number of machine learning models that can be trained in parallel, we need to calculate the total number of combinations of hyperparameters. The given hyperparameter grid includes:
Hyperparameter 1: [2, 5, 10] (3 values)
Hyperparameter 2: [50, 100] (2 values)
The total number of combinations is the product of the number of values for each hyperparameter: 3 (values of Hyperparameter 1)×2 (values of Hyperparameter 2)=63 (values of Hyperparameter 1)×2 (values of Hyperparameter 2)=6 With 3-fold cross-validation, each combination of hyperparameters will be evaluated 3 times. Thus, the total number of models trained will be: 6 (combinations)×3 (folds)=186 (combinations)×3 (folds)=18 However, the number of models that can be trained in parallel is equal to the number of hyperparameter combinations, not the total number of models considering cross-validation. Therefore, 6 models can be trained in parallel.
Reference:
Databricks documentation on hyperparameter tuning: Hyperparameter Tuning
質問 # 52
A data scientist wants to parallelize the training of trees in a gradient boosted tree to speed up the training process. A colleague suggests that parallelizing a boosted tree algorithm can be difficult.
Which of the following describes why?
- A. Gradient boosting is not a linear algebra-based algorithm which is required for parallelization
- B. Gradient boosting requires access to all data at once which cannot happen during parallelization.
- C. Gradient boosting is an iterative algorithm that requires information from the previous iteration to perform the next step.
- D. Gradient boosting calculates gradients in evaluation metrics using all cores which prevents parallelization.
正解:C
解説:
Gradient boosting is fundamentally an iterative algorithm where each new tree is built based on the errors of the previous ones. This sequential dependency makes it difficult to parallelize the training of trees in gradient boosting, as each step relies on the results from the preceding step. Parallelization in this context would undermine the core methodology of the algorithm, which depends on sequentially improving the model's performance with each iteration.
Reference:
Machine Learning Algorithms (Challenges with Parallelizing Gradient Boosting).
Gradient boosting is an ensemble learning technique that builds models in a sequential manner. Each new model corrects the errors made by the previous ones. This sequential dependency means that each iteration requires the results of the previous iteration to make corrections. Here is a step-by-step explanation of why this makes parallelization challenging:
Sequential Nature: Gradient boosting builds one tree at a time. Each tree is trained to correct the residual errors of the previous trees. This requires the model to complete one iteration before starting the next.
Dependence on Previous Iterations: The gradient calculation at each step depends on the predictions made by the previous models. Therefore, the model must wait until the previous tree has been fully trained and evaluated before starting to train the next tree.
Difficulty in Parallelization: Because of this dependency, it is challenging to parallelize the training process. Unlike algorithms that process data independently in each step (e.g., random forests), gradient boosting cannot easily distribute the work across multiple processors or cores for simultaneous execution.
This iterative and dependent nature of the gradient boosting process makes it difficult to parallelize effectively.
Reference
Gradient Boosting Machine Learning Algorithm
Understanding Gradient Boosting Machines
質問 # 53
A data scientist is developing a machine learning pipeline using AutoML on Databricks Machine Learning.
Which of the following steps will the data scientist need to perform outside of their AutoML experiment?
- A. Model evaluation
- B. Model tuning
- C. Model deployment
- D. Exploratory data analysis
正解:D
解説:
AutoML platforms, such as the one available in Databricks Machine Learning, streamline various stages of the machine learning pipeline including feature engineering, model selection, hyperparameter tuning, and model evaluation. However, exploratory data analysis (EDA) is typically performed outside the AutoML process. EDA involves understanding the dataset, visualizing distributions, identifying anomalies, and gaining insights into data before feeding it into a machine learning pipeline. This step is crucial for ensuring that the data is clean and suitable for model training but is generally done manually by the data scientist.
Reference
Databricks documentation on AutoML: https://docs.databricks.com/applications/machine-learning/automl.html
質問 # 54
......
Databricks Databricks-Machine-Learning-Associate 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
実際にあるGoShiken Databricks-Machine-Learning-Associate問題集PDFで100%合格率 保証付き:https://www.goshiken.com/Databricks/Databricks-Machine-Learning-Associate-mondaishu.html
無料Databricks Databricks-Machine-Learning-Associate試験問題と解答:https://drive.google.com/open?id=1SYu5dYr0fBa0DmJmX2SBoBTuj1Ku3-Gm